A method tells the server what you intend to do
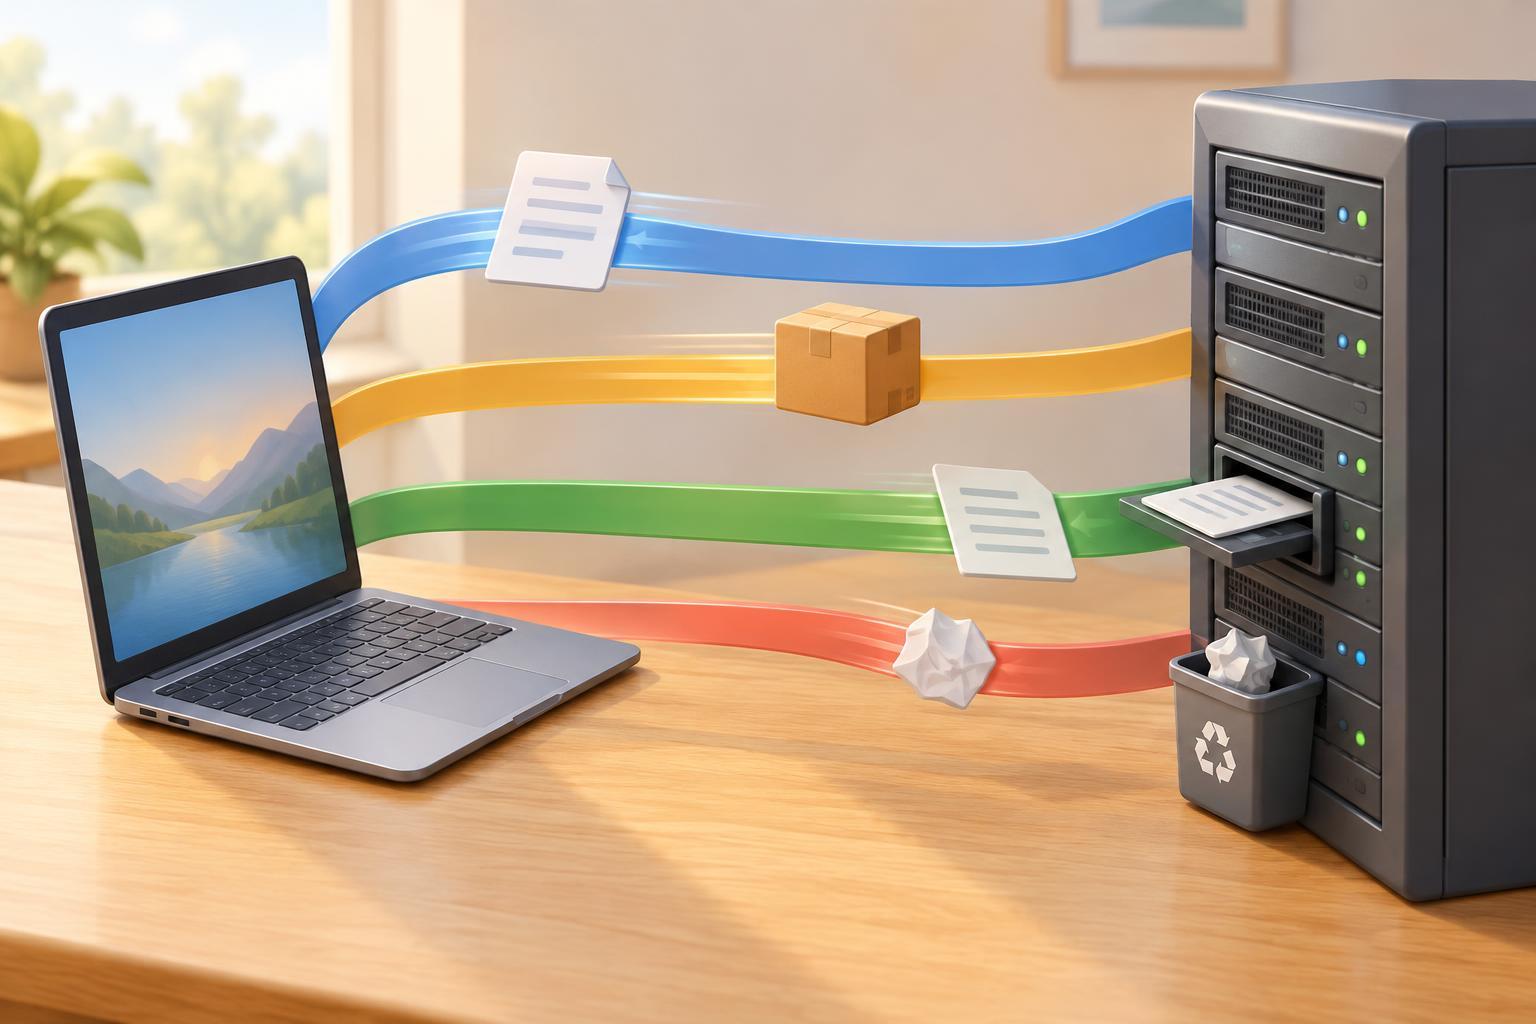
Every HTTP request has a method, a path, and usually headers. Some requests also carry a body. The method tells the server the kind of action the client intends. For example, the path /articles/42 might identify one article, while the method says whether the client wants to read, replace, or delete it. The server still decides what actually happens: choosing DELETE does not grant permission to delete anything.
GET, POST, PUT, and DELETE are commonly used when designing an API. Their meanings help people reading your code understand what to expect. They also help clients make decisions about caching and retries. For the examples below, imagine an API with a collection at /articles and an individual article at /articles/42. These paths are illustrative, not a live service, so no tools or particular software versions are needed to follow along.
Use GET to retrieve information
Use GET when the client wants a representation of a resource without requesting a change to it. GET /articles could retrieve a list, while GET /articles/42 could retrieve one article. A search can also use GET, with search terms in the URL, when running the search does not itself change server-managed data.
GET is described as safe: the client is not asking the server to change state. A server may still record a visit in a log or update internal metrics, but those are not the requested purpose of the call. This distinction matters because browsers, caches, and other software may repeat or prefetch GET requests. Do not make a GET link delete a record, charge a customer, or perform another action the user would not expect from simply opening a page. GET responses can be cached when the response’s caching rules allow it; do not assume that every GET response will be cached.
Use POST to submit an action or create something
Use POST when the client submits data for the server to process. For example, POST /articles with an article title and body might create a new article. The server may assign its identifier and return a response that tells the client what was created. POST is also suitable for actions that do not fit neatly into replacing a resource, such as submitting a contact form.
A repeated POST might repeat the action. Sending the same article-creation request twice could create two articles, depending on how the server is built. If a client must retry after a connection problem, it cannot assume the first request failed merely because it did not receive a response. Applications that need reliable retries can design safeguards, such as a request identifier that lets the server recognize a duplicate. POST does not automatically mean “create,” and it does not automatically prevent caching; its meaning and response behavior depend on the endpoint and HTTP rules.
Use PUT to create or replace a resource at a known address
PUT is useful when the client knows the resource’s address and sends the representation it wants stored there. PUT /articles/42 might replace article 42 with the article data in the request body. Whether PUT may create a resource that does not yet exist depends on the API’s design. Check the endpoint’s documentation rather than assuming every server accepts creation through PUT.
PUT is idempotent: making the same request once or several times is intended to have the same effect on the target resource. That makes a retry less likely to create duplicates than retrying a typical POST. It does not promise identical responses or mean the server cannot write a log entry each time. A common mistake is sending only a changed field to a PUT endpoint that expects a complete replacement; omitted fields might be removed or reset. Some APIs support partial changes with PATCH, a separate method.
Use DELETE to request removal
DELETE /articles/42 asks the server to remove the resource identified by that path. The server might remove it immediately, mark it as deleted, or reject the request because the client lacks permission. The method communicates the request’s intent, not a guarantee about how the data is stored behind the scenes.
DELETE is also idempotent in its intended effect: after a successful deletion, repeating the request should not delete an additional resource. The responses to the first and second requests may differ, however. One server might report success both times; another might say the resource is no longer found on the second attempt. When choosing among these four methods, ask a simple question: am I reading, submitting for processing, replacing a resource at a known address, or requesting its removal? That choice makes an API easier to understand and safer to use.